The Professor of Outputmaxxing — Anjney Midha, AMP
About this episode
The episode discusses the importance of maximizing GPU utilization in AI engineering, featuring guest Anjney Midha.
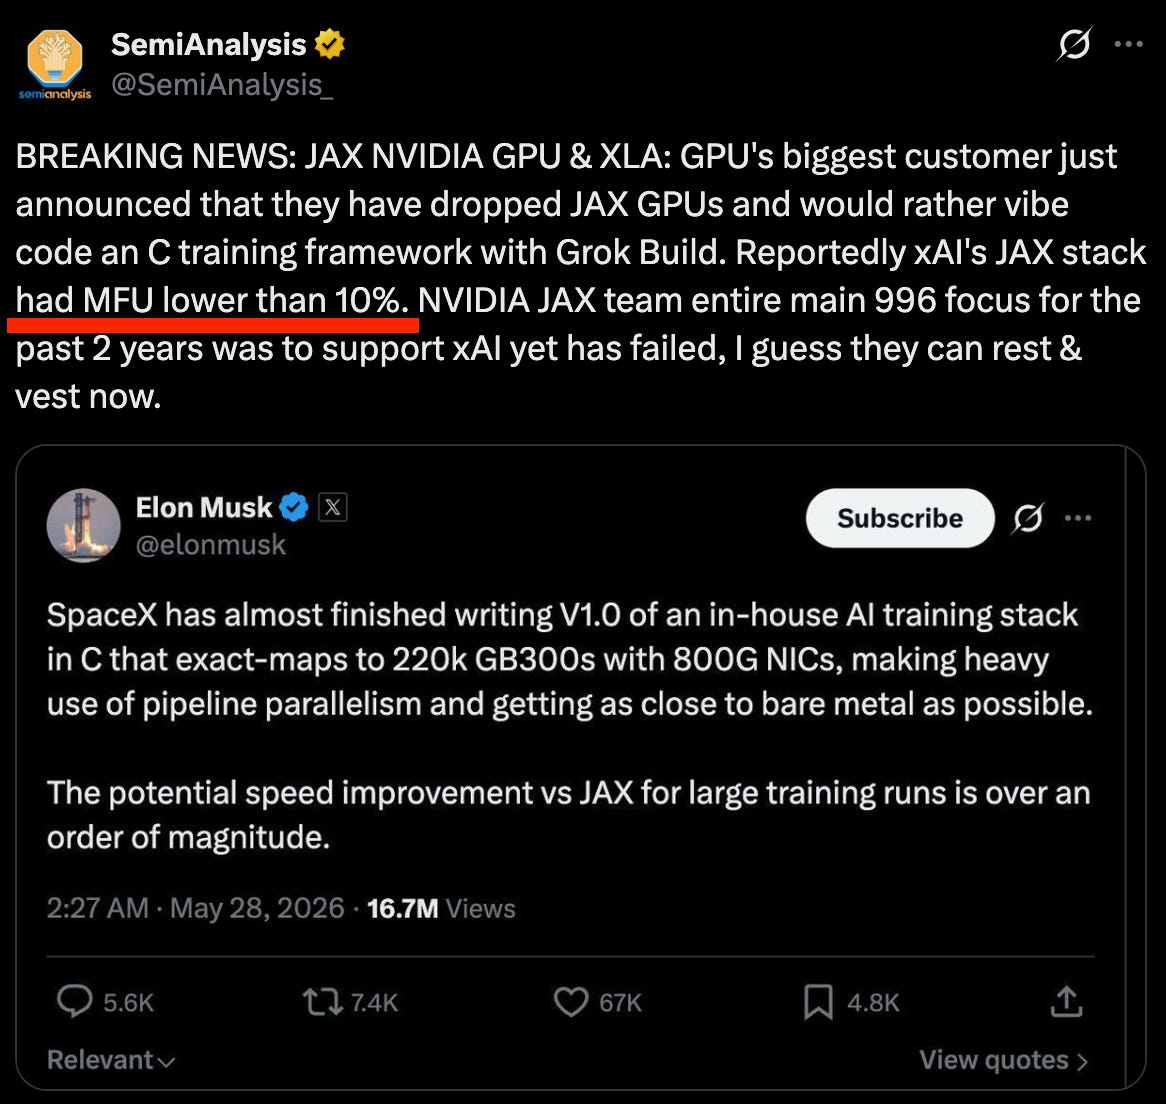
Last 4 days before regular tickets sell out at AI Engineer World’s Fair - this is the single biggest gathering of AI Engineers, Founders, Leaders, and Researchers in the world. Attendees get >$5000 worth of sponsor credits and talk tracks are looking FANTASTIC. Join us! The AI scaling debate always focuses on the question of “how do we get more GPUs?” but the better question may be: how do we make the most of ones we already have. The fact that a frontier lab like xAI could be running at sub-10% MFU (Model FLOPs Utilization) is just a hint at what the real problem may be. For context, older frontier-scale training runs were already much higher than 10%. GPT-3 was around 21% MFU . Gopher was around 32% . Megatron-Turing NLG was around 30% . PaLM reached around 46% . And our guest Anjney says best-in-class MFU today is closer to 60–70% . It’s not necessarily that xAI is uniquely incompetent (it’s clear they have talented folks) but rather the priorities may be flipped in the GPU arms race. While GPU access is a bottleneck, simply increasing CapEx won’t automatically translate to better models as frontier AI is increasingly a systems problem : scheduling, utilization, networking…
More episodes of Latent Space: The AI Engineer Podcast
- 🔬Causal Models Need Causal Data - Xaira’s X-Cell model for Drug Discovery (Bo Wang & Ci Chu, Chief Discovery Officer & Chief AI Scientist)
- 🔬 The Lab of the Future Should Feel Like a Data Center — Andy Beam & Rafa Gómez-Bombarelli, Lila Sciences
- Why AI Infrastructure must evolve for Agent Experience — Akshat Bubna, Modal CTO
- 🔬 The Coolest Diffusion Research Isn't in LLMs — Evan Feinberg & Sergey Edunov, Genesis Molecular AI
- Why the Frontier Ecosystem must be Open — Matei Zaharia and Reynold Xin, Databricks
- Red-Teaming after Mythos — Zico Kolter & Matt Fredrikson, Gray Swan
Explore listener stats, chart rankings, contacts and more on the Latent Space: The AI Engineer Podcast podcast page.